Matryoshka Attribution Finds the 1% of an AI Model That Says No
A new Stanford method ranks every part of a language model by how much it matters for a behavior. It is a real step for AI explainability, and a warning about how fragile safety training can be.
When a chatbot refuses a request, where inside the model does that decision live? A preprint posted to arXiv on September 22 by seven Stanford researchers, led by Aryaman Arora with Dan Jurafsky and Christopher Potts, offers an unusually precise answer. Their method, Matryoshka Attribution (MAttr), now sits first on the public leaderboard of the Mechanistic Interpretability Benchmark, with an average score of 5.6 on a hidden test set against 1.95 for the runner-up.
How it works
Attribution means working out which internal parts of a model caused a given output. Those parts can be attention heads (small units that decide which words to focus on), individual neurons, the connections between them, or rows of the model’s weights, which are the numbers learned in training.
The test uses pairs of prompts: an original, and a “counterfactual” version edited so the right answer changes. Patching means copying a part’s internal value from the counterfactual run into the original run. If you patch everything except a chosen handful of parts and the model still gives the original answer, that handful carries the behavior.
MAttr gives every part a single score. At each training step it picks a random budget, say 50 parts, turns the scores into a soft mask that keeps roughly the 50 highest scorers, patches the rest, and checks how far the answer drifted. It then nudges the scores to reduce that drift. Because the budget changes every step, the result is one ranking that works at every size, and the best 10 parts always sit inside the best 50.
Why it is called Matryoshka
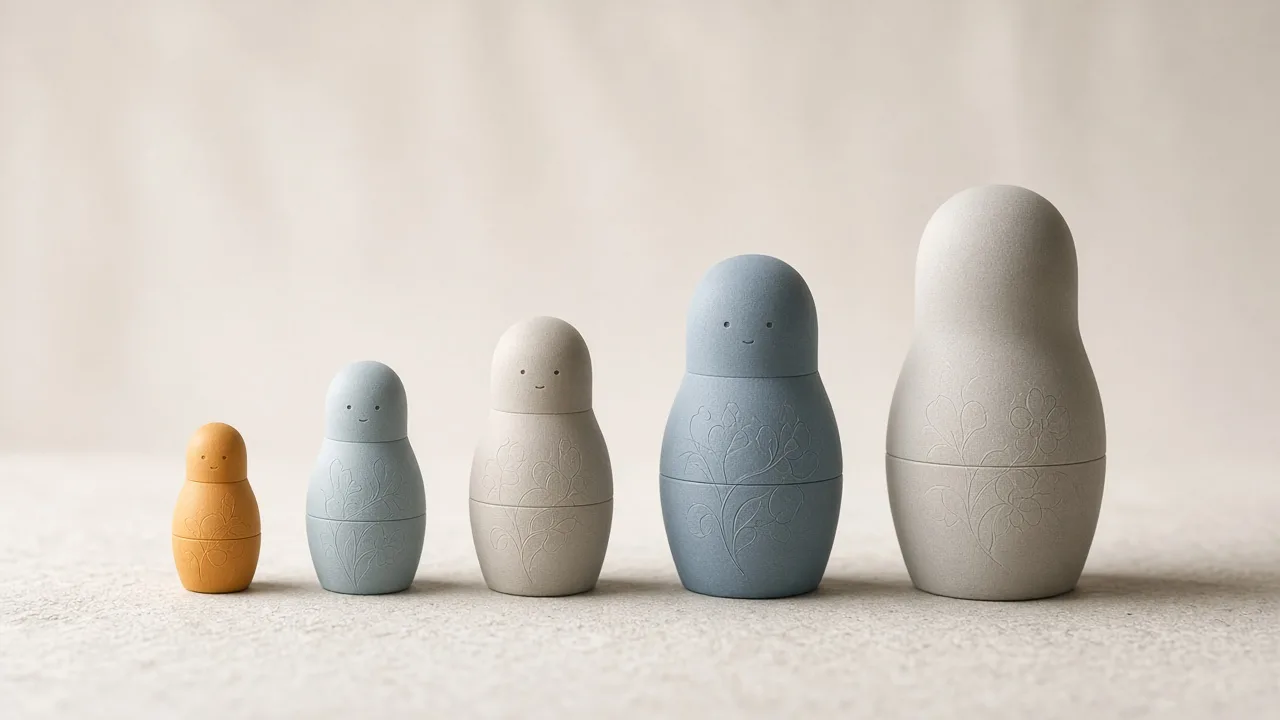
A matryoshka is a Russian nesting doll: a set of wooden dolls in which each smaller doll fits exactly inside the next larger one. MAttr’s explanations are built the same way. There are no smaller models hidden inside the AI. It is one model, and what nests is the list of parts the method picks out. The top 10 parts always sit inside the top 50, the top 50 inside the top 500, and so on. The smallest set is the core of the behavior, and each larger set adds the supporting parts around it.
Earlier methods trained a separate answer for each size, so the best 10 parts might not appear in the best 50 at all. Because MAttr’s sets always nest, an auditor can zoom in or out on one ranking and get a consistent story at every level of detail.
The benchmark, MIB, was built in 2025 by researchers led by Aaron Mueller of Boston University. It measures faithfulness: how much of the full model’s preference for the right answer a circuit (a small set of parts) preserves, checked at sizes from 0.1% to 100% of the model.
The team then applied the same idea to weights. They compared Llama 3.1 8B Instruct, which is trained to refuse harmful requests, with its base version, which was never taught to refuse. Restoring a weight means setting it back to its base value. A judge model scored the answers, and that score trained the rankings. Restoring just 1% of the weights raised the model’s harmfulness score on the StrongREJECT test from 2.6 to 84.0 while math, knowledge, and instruction-following scores stayed close to the original. Standard refusal-removal methods changed more than 27% of the weights.
Why it matters for explainability
For anyone trying to trust AI, this is progress. A regulator or buyer can ask where a behavior lives and get a short, testable list. Auditors could check whether safety is spread deeply through a model or sits in a thin, removable layer.
That is also the catch. The same tool that finds safety can strip it, and the authors warn that releasing unguarded base models next to safety-tuned ones creates exactly this risk.
The limits
This is an unreviewed preprint. The leaderboard win is on one metric of one benchmark; on MIB’s second metric, which also rewards capturing parts that hurt performance, MAttr does not lead. The refusal results cover two Llama models. And a ranked list of parts shows where a behavior happens, not why. At Predictive Systems, we see that gap between location and understanding as the next frontier for practical trust in AI.
Sources
- Aryaman Arora, Kirill Acharya, Nathan Hu, Yanzhe Zhang, Noah Goodman, Dan Jurafsky, Christopher Potts (Stanford University), “Matryoshka attribution: Learning to attribute language model outputs to representations and weights,” arXiv preprint, September 22, 2026. https://arxiv.org/abs/2609.25518
- Aryaman Arora, matryoshka-attribution code repository, GitHub, 2026. https://github.com/aryamanarora/matryoshka-attribution
- Aaron Mueller, Atticus Geiger, Sarah Wiegreffe, Yonatan Belinkov, et al., “MIB: A Mechanistic Interpretability Benchmark,” arXiv, 2025 (ICML 2025). https://arxiv.org/abs/2504.13151
- MIB organizers, “MIB Leaderboard,” Hugging Face Spaces, accessed September 26, 2026. https://mib-bench-leaderboard.hf.space/
Source: Matryoshka attribution: Learning to attribute language model outputs to representations and weights